What DNS rebinding changes
A domain name normally helps a browser find the server for a website. Its DNS answer can change, however, and a browser may make a later connection to a different IP address while still using the same domain name in the URL. DNS rebinding takes advantage of that gap between a name and the network address it currently resolves to.
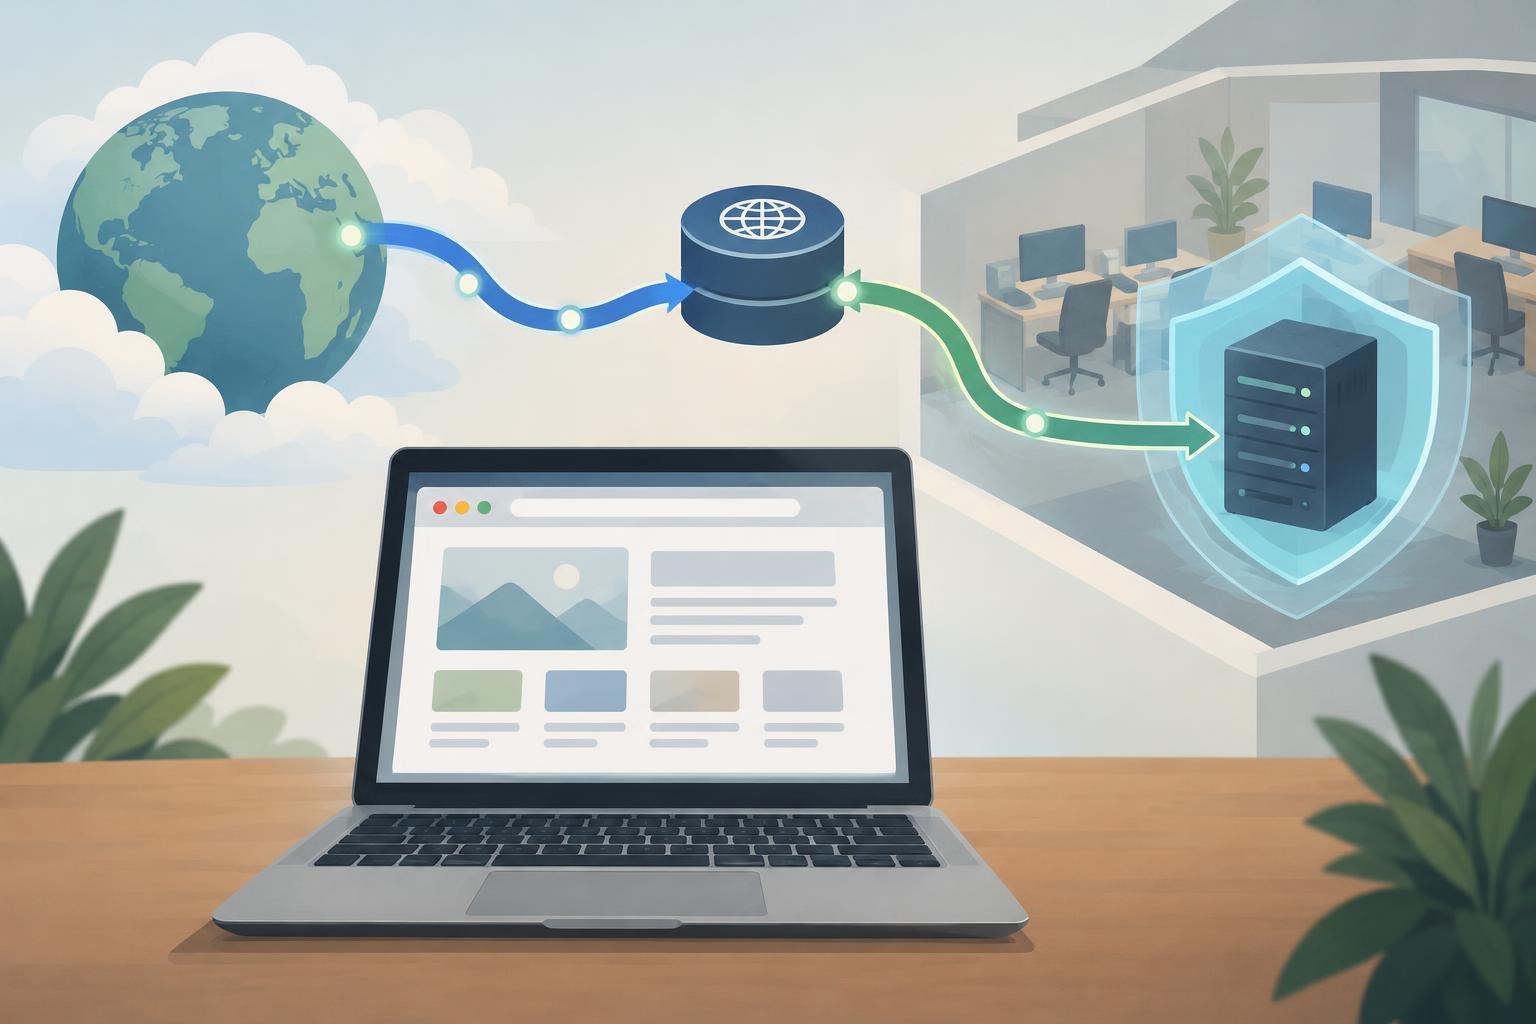
In a typical scenario, someone visits a page served from a domain controlled by an attacker. The domain initially points to the attacker’s server. Later, its DNS answer points to an address on the visitor’s private network, such as a local device or an internal web application. If the browser makes a new connection using that answer, requests intended for the attacker-controlled domain may reach the internal service instead. Whether this succeeds depends on browser behavior, network settings and the service’s own defenses.
The important distinction is that a domain name is not a permanent statement about where traffic goes. Treating it as one can give an internal application a false sense of safety.
Why a browser can be part of the path
Browsers use an origin—generally the combination of scheme, hostname and port—to decide which pages may interact with one another. The IP address reached by a connection is not, by itself, the origin shown to a web page. That distinction is useful for ordinary websites whose addresses change, but it also explains the rebinding risk: a page may continue using the same hostname after its DNS answer changes.
This does not mean DNS rebinding automatically defeats every browser restriction. Connection reuse, DNS caching, private-network protections and application responses can affect the outcome. Still, an internal service should not assume that a request arriving from a visitor’s browser is safe merely because the service is not exposed directly to the public internet. The browser may have access to network locations that a remote attacker cannot reach on their own.
For an administrator, the practical question is not just “Can outsiders connect to this address?” It is also “What happens if a browser already inside the network sends this service a request?”
Where hostname-based trust falls short
An internal web application might rely on a private IP address, a local-only deployment or a friendly hostname as its main protection. None of these proves that a request is authorized. A request delivered through rebinding can target a private address while presenting the attacker-controlled domain as the HTTP Host value. An application that accepts any Host value, or uses it only to construct links, may not notice that the request arrived under an unexpected name.
Checking the Host value against a short list of intended names can help reject this kind of request, but it is a boundary check, not user authentication. Host values can also be supplied directly by non-browser clients. Likewise, checking an Origin header can help evaluate browser-initiated requests, but an application should not treat any single header as proof of identity.
A safer design asks separate questions: Is this a name the application is meant to serve? Is the user authenticated? Is this particular action authorized? If a request changes settings or reveals sensitive information, those checks matter even when the application is usually reached only from inside a trusted network.
Build defenses in layers
Start with the application. Configure it to accept only its intended hostnames, and reject unexpected Host values rather than silently serving the same interface. Require authentication for administrative and sensitive functions, and apply authorization to individual actions. For browser-based interfaces, use appropriate protections against cross-site requests and validate request origins where that fits the application. Avoid treating “request came from a private address” as a substitute for these controls.
Network and DNS settings provide additional layers. Restrict which devices can reach management interfaces, and avoid exposing them to an entire local network when only a few administrators need access. Some DNS resolvers or security gateways can block answers that map public domain names to private addresses; their behavior varies, so such filtering should be tested rather than assumed. Browser protections may also help, but applications should not depend on every visitor running the same browser configuration.
Be cautious about simple fixes such as long DNS cache times or a single hostname check. Caching behavior differs across systems, and a hostname is an identifier, not a credential. Layered controls remain useful even if one DNS or browser defense does not apply.
A practical review for internal services
Make an inventory of web interfaces on local networks: router panels, development tools, dashboards and device administration pages are common examples. For each one, check which hostnames it accepts, who can reach it and which actions work without signing in. Pay particular attention to default installations that assume local access is trusted.
When testing your own service, use a harmless request with an unexpected Host value and confirm that the application rejects it. Then review whether sensitive pages require a valid session and whether state-changing actions have their own protections. Avoid using real credentials or changing production settings merely to demonstrate a risk.
DNS rebinding is a reminder that network location and web identity are different things. An internal address can reduce exposure, and an expected hostname can help identify a request, but neither establishes permission. Internal applications are more resilient when they verify the requested host, authenticate users and limit what each request is allowed to do.


